Page Scraper API: Extract Product Data from Any Retailer URL
The entrance to every webshop we do not have a dedicated scraper for. Pass a product URL, and /page either serves the Google Shopping data we already hold for that product, or fetches the retailer's own page live and returns structured JSON: title, price, images, description, specs, brand, EAN and availability. No custom parser needed.
Any
Retailer supported
5
Core fields guaranteed
~1-4s
Typical response
JSON
Flat structured output
Get Page Scraper data in 3 steps
Pass any product URL
Send a GET request with the full retailer product URL. No pre-configuration, no per-site parser. If we have no dedicated scraper for that retailer, this is the way in.
We route it
If we already hold Google Shopping data for that product, you get that. Otherwise /page fetches the retailer's own product page live through the enterprise endpoint and extracts the fields.
Receive flat JSON
One flat object: title, brand, gtin, image and images, description, price and currency, shipping cost, availability, seller, plus the extraction method and proxy used.
The Page Scraper listing behind the data
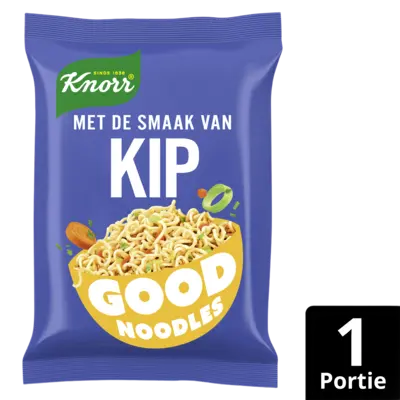
Pulled live from Albert Heijn's product page with the /page endpoint, the deep PDP view that complements the multi-seller /offers call.
 2 photos
Scraped live from Albert Heijn's product page via the /page endpoint.
Page Scraper API integration
Get started in minutes with code examples in your preferred language.
Deep PDP scrape via /page
Point /page at any retailer's product URL to pull the full listing: title, brand, EAN, price, image gallery, description and availability. This is the live example for a retailer we have no dedicated scraper for, Albert Heijn, returned in about a second.
Implementation
curl --location --request GET "https://enterprise.shoppingscraper.com/v2/live/page?url=https%3A%2F%2Fwww.ah.nl%2Fproducten%2Fproduct%2Fwi614420%2Fknorr-good-noodles-kip" \
  --header "X-API-Key: your_api_key_here"
https://enterprise.shoppingscraper.com/v2/live/page?url=https%3A%2F%2Fwww.ah.nl%2Fproducten%2Fproduct%2Fwi614420%2Fknorr-good-noodles-kip{"url": "https://www.ah.nl/producten/product/wi614420/knorr-good-noodles-kip","title": "Knorr Good noodles kip bestellen | Albert Heijn","brand": "Knorr","identifier": "wi614420","gtin": "8721317780981","gtin_extra": [],"image": "https://static.ah.nl/dam/product/AHI_6544566e6a644d6d536f615a59583956304951633667?revLabel=1&rendition=400x400_WEBP&fileType=binary","images": ["https://static.ah.nl/dam/product/AHI_6544566e6a644d6d536f615a59583956304951633667?revLabel=1&rendition=400x400_WEBP&fileType=binary","https://static.ah.nl/dam/product/AHI_6544566e6a644d6d536f615a59583956304951633667?revLabel=1&rendition=200x200_WEBP&fileType=binary"],"description": "Op zoek naar Knorr Good noodles kip? Dit product vind je in het grote assortiment van Albert Heijn. Bestel direct online!","category": null,"price": 1.19,"price_currency": "EUR","price_original": null,"shipping_cost": null,"price_with_shipping": 1.19,"availability": "InStock","condition": "NewCondition","seller": "Albert Heijn","rating": null,"review_count": null,"specs": [],"structured_data_found": ["JSON-LD", "OpenGraph", "Meta", "HTML"],"extraction_method": "JSON-LD, OpenGraph, Meta, HTML","proxy_used": "ladder:711:nl|chrome-win","duration_seconds": 3.58,"success": true,"error": null}
What you get with Page Scraper
Universal retailer fallback
This is the catch-all for the long tail. We run dedicated scrapers for the biggest retailers; /page covers every other webshop worldwide with the same request shape, so you never have to wait for a custom parser.
Live PDP, not just an aggregate
The multi-seller /offers call gives you price comparison across sellers. /page goes deep on one retailer's own listing: full description, spec sheet, every product image, and the retailer's own review score.
Structured, flat JSON
Returns a single flat object (no nesting to unwrap): title, price, price_currency, shipping_cost, price_with_shipping, image, images array, description, brand, gtin, availability, condition and seller.
Managed access
Proxy routing and browser emulation deliver consistent access to public product pages, with automatic retries. The response tells you which proxy path and extraction method were used.
Structured-data aware
Reads JSON-LD, OpenGraph, meta tags and raw HTML in that order of trust, so the fields come from the retailer's own structured markup wherever it exists.
GTIN on the way out
Where the retailer exposes it, /page returns the product's EAN/GTIN, so you can join the live listing straight back to your catalog or to a Google Shopping match.

Available data points
- Product title
- Price, currency and price with shipping
- Shipping cost (where the retailer exposes it)
- Primary image and full images array
- Full description
- Brand / manufacturer
- EAN / GTIN barcode
- Availability / stock status
- Product condition (new / refurbished / used)
- Seller / retailer name
- Rating and review count (where present)
- Specifications (key-value pairs, where present)
The entrance to every retailer we do not have a scraper for
We maintain dedicated scrapers for the largest retailers, each backed by Google Shopping data. For everything else, the long tail of webshops, /page is the single entrance. You pass a product URL and we handle it two ways: if we already hold Google Shopping data for that product we return it, and if not, we fetch the retailer's own product page live and extract the fields. Same request, same flat response, whatever the retailer.
- No per-site configuration or custom parser needed
- Works with JavaScript-rendered pages (SPA, React, Angular)
- Managed proxy routing with automatic retries
- The response names the extraction method and proxy path used
How /page differs from /offers
The two endpoints answer different questions. /offers searches by EAN across Google Shopping and returns every seller carrying the product, with each seller's price, so it is built for price comparison. /page takes one retailer URL and returns the deep product detail from that single listing: description, spec sheet, all images, and the retailer's own review score, data the multi-seller call does not carry. Use /offers to compare, /page to go deep on one retailer.
- /offers: one EAN, many sellers, comparison across Google Shopping
- /page: one URL, one retailer, full product detail page
- /page returns fields /offers does not: full description, spec sheet, image gallery, retailer review score
Endpoint details
The live PDP path is a GET request with the target URL as a query parameter and your key in the X-API-Key header. It handles rendering, cookies and proxy rotation for you.
- Endpoint: https://enterprise.shoppingscraper.com/v2/live/page?url={encoded_url}
- Authentication: X-API-Key request header
- Response: one flat JSON object with the extracted fields
- Core fields returned: image, price, availability, description, plus title, brand, gtin, images and seller
Retailers verified with the /page endpoint
We run dedicated scrapers for the largest retailers and validate the long tail against /page directly. These 148 retailers have been confirmed to return the core fields (image, price, availability, description) from a live /page call. The list is not a limit: /page works with any retailer product URL, this is simply the set we have verified so far, grouped by market.
- Netherlands (25): ah.nl, badkamerxxl.nl, bosrand.nl, coolblue.nl, decathlon.nl, douchezaak.nl, fonq.nl, galaxus.nl, hornbach.nl, hornbad.nl, intertoys.nl, jumbo.nl, kruidvat.nl, lidl.nl, mediamarkt.nl, mondiaz.nl, partywinkel.nl, sanexo.nl, sanispecials.nl, sanitairwinkel.nl, sony.nl, technim.nl, tegeldepot.nl, tegelstudio.nl, wehkamp.nl
- Belgium (3): badkamerdepot.be, badkamerxxl.be, saniweb.be
- Germany (20): aponeo.de, brickmerge.de, conrad.de, expert.de, fliesen-supermarkt.de, fliesenrabatte.de, galaxus.de, kaufland.de, manomano.de, mediamarkt.de, mondial-badmoebel.de, mueller.de, mycare.de, otto.de, reichelt.de, rockyshop.de, saniweb.de, saturn.de, thalia.de, voelkner.de
- France (9): auchan.fr, carrefour.fr, cmesmat.fr, joueclub.fr, laredoute.fr, redbull-france.fr, rueducommerce.fr, sawiday.fr, terraled.fr
- Spain (13): alijuguetes.es, alternate.es, asianorigins.es, carrefour.es, drim.es, elcorteingles.es, farmaciacuestalavilla.es, fatyzoo.es, idealo.es, juguetilandia.es, mediamarkt.es, mondiaz.es, toysrus.es
- Italy (11): alternate.it, carrefour.it, eprice.it, manomano.it, mediaworld.it, pinalli.it, shopincasa.it, tuttofarma.it, unieuro.it, vendiloshop.it, yves-rocher.it
- United Kingdom (15): argos.co.uk, armanibeauty.co.uk, blockp.co.uk, currys.co.uk, gamescrusade.co.uk, headrecords.co.uk, mrcentralheating.co.uk, myshop.co.uk, next.co.uk, sealantsandtoolsdirect.co.uk, superdealwholesale.co.uk, toystreet.co.uk, turnituprecords.co.uk, very.co.uk, verycosmetics.co.uk
- Poland (1): lazienkaplus.pl
- Finland (1): stark-suomi.fi
- Australia (1): myer.com.au
- United States and International (48): adrihosan.com, allbirds.com, amazon.com, apple.com, asda.com, beautyplaza.com, bestbuy.com, bol.com, boots.com, bosch-professional.com, costco.com, cultura.com, darty.com, dior.com, farmaciaforyou.com, fnac.com, greatecno.com, guanxe.com, hamleys.com, handmadebyrobots.com, hm.com, homedepot.com, ikea.com, ionahomestore.com, johnlewis.com, jomashop.com, juguetilandia.com, king-jouet.com, lamy.com, lego.com, llmedico.com, logitech.com, macys.com, maisondelatendance.com, marvimundo.com, mattel.com, mibricolaje.com, multitanks.com, nordstrom.com, pccomponentes.com, playstation.com, roughtrade.com, shopflamingo.com, smythstoys.com, target.com, tusmejoresfragancias.com, walmart.com, wayfair.com
Frequently Asked Questions
When should I use /page instead of a dedicated scraper?+
Use a dedicated scraper when one exists for your retailer (they are backed by Google Shopping data). Use /page for every other webshop. It is the universal fallback: the same request shape works on any retailer product URL, so you do not have to wait for us to build a custom parser.
What does /page return that /offers does not?+
/offers returns multiple seller offers for one EAN across Google Shopping, built for price comparison. /page goes deep on a single retailer's own product page and returns the full description, the specification sheet, every product image, and the retailer's own review score. Use /offers to compare sellers, use /page for detailed product data from one URL.
Which fields are guaranteed?+
We treat image, price, availability and description as the core set and validate retailers against them. Title, brand, seller and (where the retailer exposes it) EAN/GTIN and shipping cost come back too. Shipping cost is not always present: some retailers, Albert Heijn for example, simply do not publish it on the product page, so it can be null.
How is reliability managed?+
The endpoint includes managed proxy routing and browser emulation for consistent access to public product pages, with automatic retries. The response reports the proxy path and the extraction method (JSON-LD, OpenGraph, meta, HTML) so you can see where each field came from.
How much does a page scrape cost?+
Each page scrape is metered in credits, shared across all ShoppingScraper endpoints. Plans start at 150,000 credits per month (Enterprise Starter, EUR 799/month) and scale to 500,000+ on Enterprise Pro (from EUR 1,499/month, yearly contract).
Scrape any retailer's product page today
100 free API calls. No credit card required. Works with any webshop.